Tool-Calling Agent Guardrails and Retry Patterns September 2026
Tool-calling agents don't usually fail because the model breaks. They fail because a tool returns something slightly off, the agent treats it as valid, and every step after that builds on a cracked foundation. By the time the session ends, you've got a completed workflow and the wrong result. Fixing this requires working through validation, retry logic, and guardrails as a connected system, not as three separate afterthoughts.
TLDR:
- A 20-step agent workflow at 95% per-step reliability succeeds only 36% of the time overall.
- Production failures cluster into four categories: reasoning drift, tool call failures, context saturation, and goal misalignment -- each requiring a different detection strategy.
- Guardrails inside the LLM are soft rules; only application-layer checks and API gateway enforcement block unauthorized calls independent of model state.
- Classify failures before retrying: schema mismatches and permission errors are not retryable, and sending the same malformed call three more times burns tokens with no recovery.
- Openlayer applies pre-deployment CI/CD gates and production-side blocking that suspends execution when intent-to-tool alignment confidence drops below 0.75 or the requested tool falls outside the agent's registered allowlist.
Why tool-calling agents break in production
The failure math is unforgiving. 63% of complex tasks fail, and the cause is rarely a catastrophic model collapse. It's interaction-level breakdowns between steps: a tool returns an unexpected schema, the agent misinterprets the result, and the next call goes sideways on a bad assumption.
Compounding makes this worse in a way that isn't obvious at the step level. A 20-step workflow running at 95% per-step reliability succeeds only 36% of the time overall. Each step looks fine in isolation. The workflow fails routinely. That gap between individual-step confidence and end-to-end reliability is where most teams get surprised in production.
The four production failure categories
Production failures cluster into four categories, each with a different signature in your traces.
- Reasoning drift happens when the agent's internal reasoning gradually diverges from the original task. A customer support agent tasked with canceling a subscription starts attempting a refund instead. No single step was wrong, but the goal shifted mid-chain.
- Tool call failures are the most visible: malformed arguments, schema mismatches, API errors the agent doesn't handle cleanly. Tool calling fails somewhere between 3% and 15% of the time in production, with some workflows seeing much higher rates depending on the tool surface.
- Context window saturation is subtler. As conversation history, tool results, and intermediate outputs accumulate, earlier instructions get pushed toward the edge of the context window. The agent stops behaving consistently because it no longer has full access to its own task state.
- Goal misalignment shows up at the session level. The agent completes every individual step correctly but produces an outcome the user never asked for. No individual tool call throws an error, which makes this the hardest category to catch.j
The table below provides a high-level overview of the failure categories, their visible signals, and where each failure tends to show up first.
| Failure Category | Visible Signal | Where It Shows Up |
|---|---|---|
| Reasoning drift | Goal shift mid-chain | Mid-session trace divergence |
| Tool call failures | Schema errors, API exceptions | Individual span errors |
| Context saturation | Instruction inconsistency late in session | Late-turn behavior changes |
| Goal misalignment | Correct steps, wrong outcome | Session-level evaluation |
Tool call validation: Before the agent sends the request
Pre-execution validation is cheap. Validation after a bad tool call has fired against a production database is not.
The first layer is schema validation: confirm the agent's requested arguments match the tool's expected types, required fields, and value ranges before the call goes out. This catches the majority of malformed-argument failures at zero cost to the downstream system.
Allowlist enforcement sits on top of that. Even a perfectly formed call is a problem if the agent is invoking a tool outside its permitted scope. The OWASP AI Agent Security Cheat Sheet identifies tool abuse and privilege escalation as key agent risks. An explicit allowlist at the call boundary, checked before execution, closes that surface.
The harder class of errors is semantic: a valid tool, valid arguments, wrong context. A delete_record call with a correctly typed record ID, issued at the wrong point in a workflow. Schema validation passes. The call should not have been made. Catching this requires intent-to-tool alignment checks, blocking when alignment confidence falls below a defined threshold.
The calibration tradeoff is real: for read-only tools, permissive thresholds are acceptable. For any tool that writes, deletes, or calls an external API, stricter thresholds and explicit allowlists are worth the occasional false positive.
Output validation: Catching failures after the tool returns
A tool call that returns HTTP 200 is not a tool call that succeeded in any meaningful sense. The API responded. The output might still be stale, truncated, out of domain, or semantically disconnected from what the agent actually needed.
There are three levels of output validation worth building explicitly.
- Schema conformance is the first check. Did the response match the expected structure? Missing fields, null values where the agent assumes a populated value, type mismatches. These are fast, deterministic, and catch a meaningful slice of downstream problems before they propagate.
- Semantic plausibility is harder. A search tool returns results, but none are relevant to the query. A data lookup returns a record from the wrong account. The response parses fine, but the agent should not act on it, a pattern closely related to LLM hallucination in production. Catching this requires comparing the returned output against the original task specification: does this response actually serve the step it was called for? If alignment falls below threshold, treat the call as a soft failure and decide whether to retry, reroute, or escalate.
- Confidence gating applies when tools return probabilistic outputs or ranked results. A retrieval tool returning three low-scoring chunks should not be treated the same as one returning three high-confidence matches. Gating on a minimum confidence floor before passing results downstream prevents the agent from building reasoning chains on shaky retrieved evidence.
The structural point: error handling that only catches exceptions misses the majority of output-layer failures. Most bad tool outputs return cleanly. The validation layer has to treat a successful API response as the start of output evaluation, not the end of it.
Retry logic that does not make things worse
Retrying a failed tool call without diagnosing the failure first is how a recoverable error becomes an expensive loop.
The starting classification is whether the failure is retryable at all. Rate limits and transient network errors are retryable. A schema mismatch or a permission error is not; sending the same malformed call three more times burns tokens while guaranteeing the same result. Classify first, retry second.
For retryable failures, exponential backoff with jitter is the standard: wait times grow between attempts, and random jitter prevents multiple agents from hammering the same endpoint in synchronized waves. Avoid exponential backoff for time-sensitive workflows where a delayed retry is worse than a fast fail and human escalation.
Every retry loop needs two limits:
- A per-call retry budget, typically two to three attempts for most tool types
- A session-level token budget that halts retrying when cumulative cost crosses a defined ceiling
When a tool call exhausts its budget, the decision is whether to replan: return to the task level, assess whether an alternative tool or path can satisfy the step, and only then attempt further calls. Retrying at the tool level and replanning at the task level are structurally different recovery strategies; conflating them produces agents that spin.
For low-stakes read operations, a generous retry budget is reasonable. For write operations or external API calls with side effects, keep the budget tight and escalate to a human review queue on exhaustion.
Context engineering and the compounding failure problem
Context accumulates faster than most agent implementations account for. Tool results, intermediate reasoning, failed attempts, and prior conversation turns compound across a multi-step workflow until the context window holds as much noise as signal, and the agent's behavior degrades not because anything broke, but because it can no longer see its own task clearly.
Anthropic frames this precisely: context engineering is about "what configuration of context is most likely to generate desired behavior" -- meaning the composition of what the agent sees at each step is an active design decision, not a byproduct of letting the conversation grow. That framing moves context management from a cost concern into a reliability concern.
Three strategies tackle this structurally:
- Prune irrelevant history. Tool outputs the agent has already acted on carry diminishing value; retaining them displaces the current task goal toward the context boundary without improving reasoning quality.
- Summarize completed sub-tasks. A finished retrieval step needs a concise summary of what was found and decided, not its full result set, so the active reasoning window stays focused on the current step.
- Anchor the task goal explicitly at each step. As accumulated outputs grow, the original instruction drifts toward the context edge. Re-anchoring it maintains behavioral consistency across long chains.
Context saturation throws no error and triggers no API failure. The agent keeps operating while its reasoning degrades: a silent failure mode that only surfaces at the session-evaluation level.
Where guardrails should live in the architecture
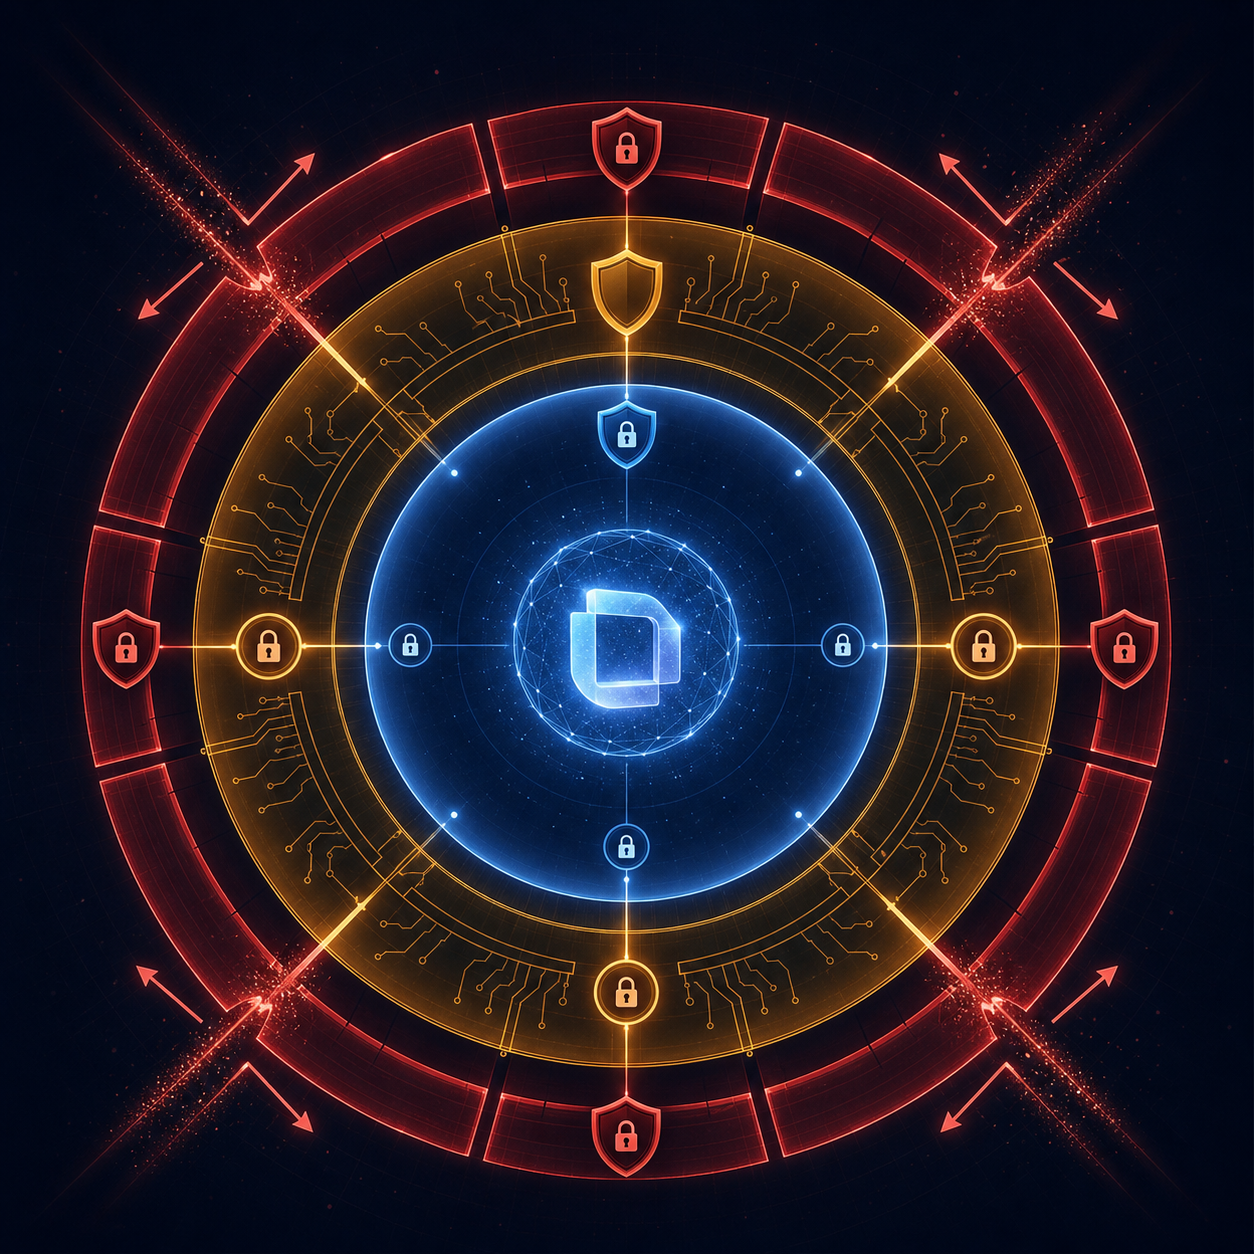
LLM guardrails placed inside the LLM itself (system prompt instructions like "never call delete tools") are soft rules. They shape behavior under normal conditions but do not enforce anything when the model has drifted from its intended goal or been prompt-injected into a different task frame. Asking a hijacked model to self-police is precisely the gap.
Three placement options exist, each stopping a different class of failure:
- Prompt-level rules (inside the LLM): catch predictable misbehavior under benign inputs. Fast, zero-latency, easy to configure. Bypassed by prompt injection, goal drift, and context saturation.
- Application code checks (pre/post tool call): schema validation, allowlist enforcement, output conformance checks. Deterministic and model-agnostic. Cannot reason about intent without additional logic.
- API gateway layer (between agent and tool endpoints): hard enforcement the agent cannot override. Blocks calls to unauthorized endpoints before they execute, independent of model state.
Any guardrail running inside the same model it is guarding inherits that model's failure modes. According to OWASP's agentic AI threat guidance, defense-in-depth controls including tool sandboxing and input validation are the recommended mitigation for exactly this attack chain. In practice, all three layers are complementary: prompt-level rules handle the common case cheaply, application-level checks catch schema violations deterministically, and gateway enforcement covers what the other two cannot reach.
Synchronous vs. asynchronous guardrail evaluation
Choosing the wrong evaluation mode for a given check means either unnecessary slowdowns or missing your enforcement window entirely. Synchronous checks run in the request path and add latency to every call they touch; asynchronous checks run after delivery and add none.
Synchronous checks are those where a wrong output reaching the user constitutes the failure:
- PII detection in LLM outputs in tool call arguments and response payloads, where exposure is the harm
- Prompt injection screening on incoming inputs before any tool logic executes
- Output schema validation before delivery, catching malformed payloads the downstream system cannot handle
- Allowlist verification confirming a tool call is permitted before it fires
Once the response is delivered or the tool has executed, the damage is done. Synchronous placement is the only mode that constitutes enforcement, not mere observation.
Asynchronous evaluation covers checks where blocking delivery adds cost without adding protection:
- LLM-as-a-judge scoring for output quality and groundedness
- Session-level coherence and goal achievement metrics
- Conversation completeness and task progression analysis
These produce signals for monitoring, drift detection, and regression evaluation. Running them after delivery preserves that value without affecting p95 latency.
Each synchronous check adds to tail latency, and that cost compounds across a multi-check pipeline. Keep the synchronous layer to checks that strictly require blocking behavior. Anything that informs quality measurement or post-deployment review belongs in the async path.
Prompt injection and tool abuse: The security layer of reliability
Prompt injection in a single-turn interface produces a bad response. In an agent, it redirects tool calls, and those calls execute before anyone reviews the output. That gap is not a severity gradation; it is a structural difference in what the failure actually is.
The OWASP Top 10 for Agentic Applications 2026 lists prompt injection as the leading risk for deployed agents. The specific threat is indirect injection: malicious instructions embedded in content the agent retrieves (a document, an API response, a fetched web page), not in user input. The model cannot distinguish "content to reason about" from "instruction to execute" without an external verification layer.
Three defenses operate at different points in the call chain:
- Input validation on every data source entering the context window, before the agent processes it. Retrieved chunks, API payloads, and external documents are untrusted until screened.
- Output verification against the original task specification. Unexplained deviations from the assigned goal are blocked before execution, catching injections that cleared the input layer.
- Least-privilege tool scope via explicit allowlists enforced at the gateway layer, outside model control. A fully compromised agent cannot execute an unauthorized tool call if the allowlist holds.
Tool privilege escalation follows a similar pattern: an agent with broad access incrementally invokes higher-privilege tools than its task requires. The same external allowlist mechanism, scoped per agent role, closes that vector. Human-in-the-loop escalation applies when injection confidence is high but tool scope is ambiguous; blocking too aggressively on uncertain signals degrades usefulness, so escalating to a reviewer preserves the control without halting the workflow entirely.
Bounded autonomy: Designing agents that know when to stop
Giving an agent an unlimited step budget is an agentic AI risk decision, not a feature. Without explicit stop conditions, a stuck agent keeps trying: burning tokens, accumulating failed tool calls, and compounding context noise until the session errors out or produces something the user never asked for.
Anthropic's guidance on building effective agents is direct: the most successful implementations used simple, composable patterns over complex autonomous frameworks. Bounded autonomy applies that principle to execution scope; the agent operates freely within defined limits and escalates outside them.
Three stop conditions belong in every agent implementation:
- A step budget: a maximum number of tool calls or reasoning turns per task. When the agent hits it without completing the goal, it surfaces to a human reviewer instead of continuing.
- A confidence floor: if intent-to-action alignment drops below a defined threshold at any step, execution pauses. Continuing on low confidence usually extends a mistake; it does not correct it.
- A retry exhaustion path: when a tool call exhausts its retry budget, the agent should replan or escalate instead of failing silently. A silent failure with no user signal is worse than a visible one.
Graceful degradation is distinct from failure. An agent that hits a confidence threshold breach has not failed; it has reached the boundary of its authorized autonomy. The right design returns a partial result with a clear handoff state: what was completed, what wasn't, and what a human reviewer needs to resolve. Build that handoff explicitly as an architectural output, not an error condition.
Observability patterns for multi-step agent workflows
Span-level tracing is the minimum viable unit for AI agent observability in tool-calling agents. A single session trace showing inputs and outputs without intermediate steps tells you the workflow failed. It does not tell you which tool call produced the bad assumption the next three steps built on.
Each tool invocation should emit its own span: the tool name, arguments sent, response received, latency, and exit status. Those spans chain into a session-level trace that shows the execution path as a sequence. That sequence view is where failure signatures become readable through LLM trace visualization. A context saturation failure looks different from a tool API failure, and neither looks like a model reasoning failure when you can see the full step chain.
Three trace patterns to build explicitly:
- Typed spans per call category: distinguish LLM inference spans from tool call spans from handoff spans. Mixing them makes it impossible to isolate which class of operation produced the failure.
- Intent-to-output attribution at each step: record what the tool returned and what the agent was trying to accomplish. When a step fails, this tells you whether the model reasoned incorrectly or the tool returned something plausible but wrong.
- Session-level aggregation: step-level spans feed a session summary covering total tool calls, retry count, first failure point, and final goal achievement status, which makes session evaluation tractable without manually reconstructing chains from raw spans.
Standardizing this structure across teams is where OpenTelemetry semantic conventions apply: The OpenTelemetry semantic conventions for AI agents provide the structural anchor here: standardized span attributes for LLM calls, tool use, and agent operations keep traces portable across backends and interpretable without custom parsing logic. Adopting the conventions upfront costs little; retrofitting them after a production incident costs considerably more.
How Evaluation Connects to Production Reliability
Agent evaluation and production monitoring cover different failure classes by design. They are not redundant layers.
Pre-deployment catches regressions against known patterns: misconfigured prompts, threshold violations on held-out datasets, tool selection errors on synthetic adversarial inputs. Every test in that suite was written by a human reasoning about what could go wrong before seeing real traffic.
Production monitoring catches what synthetic benchmarks cannot generate: reasoning drift as input distributions shift, tool call errors on edge-case argument combinations, session-level goal misalignment invisible at the individual turn. That structural difference means a pre-deployment suite, however thorough, does not shrink production's failure surface without active maintenance.
The mechanism connecting the two is converting annotated production failures into regression tests. When a production trace surfaces a new failure pattern, that trace becomes a test case. Input, expected behavior, and observed deviation get codified and added to the pre-deployment suite. The eval library grows from real failures, not guesses.
Three things make this loop function:
- Failure annotation in production traces, distinguishing tool call failures from reasoning drift from goal misalignment, so the right test structure gets generated for each category
- Evaluation coverage at the session level, beyond the turn level, since goal misalignment only manifests across the full execution path
- A deployment gate that runs the updated regression suite before any agent change ships, blocking promotion when annotated failure patterns recur
How Openlayer handles tool-calling reliability end to end
Openlayer treats the reliability problem as a single continuum, not a set of separate tooling concerns at each layer.
Pre-deployment gates run over 175 pre-built tests covering tool-call correctness, prompt injection resistance, and PII leakage, applied as hard CI/CD evaluation gates that block merges when thresholds fail. In production, a dedicated unauthorized tool call test suspends execution when intent-to-tool alignment confidence drops below 0.75 or when the requested tool sits outside the agent's registered allowlist. Each block event generates an audit trail entry carrying the agent ID, requested tool, alignment score, and task context automatically.
At the enforcement layer, the five-action taxonomy of allow with logging, warn, block, redact, and escalate gives teams granular control over the experience-versus-risk tradeoff. The escalate action routes to human review for cases where automated confidence is insufficient and a wrong output carries direct harm.
Synchronous blocking checks run in the request path; asynchronous session-level evaluation across 13 session-level metrics does not. LLM-as-a-judge scoring stays out of the synchronous path entirely, keeping tail latency from compounding across a multi-check pipeline while preserving quality signals for monitoring and regression.
Sequence-level monitoring tracks tool calls, intermediate outputs, and state changes as a unit across full execution paths. That trace fidelity is what makes it possible to distinguish a model reasoning failure from a tool API failure from a context saturation failure without reconstructing the session manually from raw spans.
Final Thoughts on Agent Guardrails and Execution Reliability
Building agents that work in production means accepting that your reliability number is the product of every step's reliability, and designing your controls accordingly. Guardrails at the prompt level, application code, and gateway layer each catch different failure classes, and none of them fully substitute for the others. Start with the failure categories most likely to show up in your specific agent architecture, instrument them with typed spans and session-level metrics, and build your eval loop from real production traces and not synthetic ones. Connect with the Openlayer team to see how Openlayer's unified evaluation, observability, and governance platform can close the gap between step-level confidence and end-to-end reliability.
FAQ
Do real-time PII checks and guardrails add latency to AI agent responses, or can they run asynchronously?
It depends on whether a wrong output reaching the user or downstream system constitutes the failure. PII detection in tool call arguments, prompt injection screening, allowlist verification, and output schema validation must run synchronously in the request path, because once the tool has executed or the response has been delivered, the damage is done. LLM-as-a-judge scoring, session-level coherence metrics, and goal achievement analysis run asynchronously after delivery, adding no latency to the live call. Keep the synchronous layer to checks that strictly require blocking behavior; anything that informs quality measurement or post-deployment review belongs in the async path.
How do you enforce hard guardrails on AI agent tool calls when the only controls in place are soft rules set inside the LLM itself?
Prompt-level instructions are soft rules that shape behavior under normal conditions but provide no enforcement when the model has drifted or been prompt-injected into a different task frame. Hard enforcement requires controls outside the model: application-layer checks and a gateway layer that blocks unauthorized calls independent of model state. See the Where guardrails should live section for the full breakdown of all three layers.
How do I implement reliable tool-calling agents with validation, retries, and guardrails?
Pre-execution schema validation catches malformed arguments before they reach a production system; allowlist enforcement at the call boundary closes the tool abuse surface. For retries, classify the failure before retrying, because a schema mismatch or permission error is not retryable, and sending the same malformed call three more times burns tokens while guaranteeing the same result. Set both a per-call retry budget (two to three attempts for most tool types) and a session-level token budget that halts retrying when cumulative cost crosses a defined ceiling. Guardrails belong at all three layers: prompt rules for common cases, application-layer checks for deterministic schema and allowlist enforcement, and a gateway layer for hard blocks the agent cannot override.
What are the biggest tool-calling reliability risks enterprises face when deploying AI agents in production?
Tool calling fails somewhere between 3% and 15% of the time in production, and the compounding math described above makes this much worse across multi-step workflows. The four failure categories that drive this are reasoning drift (goal drifts mid-chain without any single step throwing an error), tool call failures (schema mismatches and API errors), context window saturation (earlier instructions getting displaced as outputs accumulate), and goal misalignment (every step completes correctly but the session outcome is wrong). Goal misalignment is the hardest to catch because no individual tool call fails, it only surfaces at the session evaluation level, not in per-span traces.
What does distributed tracing across multi-agent workflows look like in practice with OpenTelemetry?
Each tool invocation should emit its own typed span, capturing tool name, arguments sent, response received, latency, and exit status, that chains into a session-level trace showing the full execution path as a sequence. Separate LLM inference spans from tool call spans from handoff spans; mixing them makes it impossible to isolate which class of operation produced the failure. At the session level, aggregate total tool calls, retry count, first failure point, and final goal achievement status so session evaluation is tractable without manually reconstructing chains from raw spans. The OpenTelemetry semantic conventions for AI agents provide standardized span attributes for LLM calls, tool use, and agent operations, and adopting them upfront keeps traces portable across backends and interpretable without custom parsing logic.