Enterprise AI Governance: Who Owns What in 2026
A proposed class action filed in San Diego Superior Court in November 2025 alleges that Sharp HealthCare used Abridge, an AI medical scribe, to record patient-clinician conversations without notice or consent starting around April 2025, and that the notes the tool generated falsely stated patients had been informed and had agreed. The claims are allegations, not findings, but the failure they describe is a familiar one: the documented consent step said one thing, and the system in the exam room did another. This is exactly the kind of failure an AI governance operating model is designed to catch, because it assigns a named owner to the approval, requires evidence before a tool goes live, and ties the written policy to a control that actually runs. (AI Incident Database, Incident #1754, https://incidentdatabase.ai/cite/1754/)
This post gets into who should own what, how intake and approval workflows should route by risk, and what makes the difference between a governance model that holds under audit and one that only holds on paper.
TLDR:
- An AI governance operating model defines who decides, on what evidence, and how that decision gets enforced. A policy document alone cannot answer those questions
- Wrong operating model choice costs 12 to 18 months of rework rebuilding accountability structures that should have been defined before the first production deployment
- Hub-and-spoke scales best for enterprise programs: the center sets standards and regulatory mappings, domains execute without routing every decision back to a central committee
- Agentic AI breaks traditional governance entirely. Tool calls execute before any reviewer can intervene, requiring explicit allow lists and sequence-level monitoring
- Openlayer maps risk classification at intake and converts approved policy into runtime enforcement decisions at the API boundary, with test results and approvals written to the same audit trail
What an AI Governance Operating Model Actually Is
A governance framework tells you what responsible AI looks like. An AI governance operating model tells you who decides, when, on what evidence, and how that decision gets enforced.
The distinction matters more than it sounds. As Bradshaw.cloud puts it: "An organisation can have an AI policy, a risk committee and a model register, and still be unable to answer who approves a new agent with access to customer data and the ability to send external emails. Legal assumes product owns it. Product assumes security signed it off. Security assumes the model team assessed it. The system goes live because everyone has a plausible reason to think someone else is responsible." That's an operating model failure, not a policy failure.
Governance organized around documents produces exactly this outcome. Policies specify principles; registers catalog systems; committees deliberate. But none of those artifacts answer the practical question: which specific person, with which authority, blocks or approves this deployment today?
The operating model fills that gap. It defines decision rights, the evidence required to exercise them, the workflow that routes a decision to the right owner, and the enforcement mechanism that makes the outcome stick.
Why Existing Governance Models Break Under AI Scale
Traditional IT governance assumes a relatively stable asset base: audit systems on a schedule, route change requests through a committee, document approvals after the fact. AI programs break each of those assumptions at once.
Models update continuously. Agents act in milliseconds. New use cases enter production through product teams, data science teams, and business units running on different review cadences with different risk tolerances, a problem that compounds once third-party AI and vendor governance enters the mix. The result is AI governed by whoever moved last without objection.
Three failure modes appear consistently once AI scales past early experimentation:
- Decision ownership vacuums, where no role has unambiguous authority to block a deployment. Legal assumes product approved the risk. Product assumes security reviewed the model. The system goes live on implied consent.
- Review cycles that can't match execution speed. A governance committee that meets bi-weekly cannot govern an agentic system calling external APIs hundreds of times per day. The exposure window opens and closes repeatedly before any review occurs.
- Policy without enforcement. A documented principle like "AI systems must not expose PII" carries no real weight unless something actually stops a non-compliant output before it leaves the system. Policy describes the intent; enforcement determines whether it holds.
Picking the wrong AI governance tool to fix these failures compounds them. According to AI Assembly Lines, choosing the wrong AI operating model costs 12 to 18 months of rework rebuilding accountability structures that should have been defined before the first production deployment.
The governance platform market has matured around two dominant approaches to this problem. Credo AI and IBM watsonx.governance both center on policy documentation and model risk workflows: Credo AI provides a structured policy and compliance layer with model cards, risk assessments, and stakeholder reporting; IBM watsonx.governance offers model lifecycle management, factsheet generation, and regulatory alignment tooling across the IBM stack. Both are serious governance tools for organizations that need a documented policy posture. The architectural gap that matters for operating model enforcement is that neither provides runtime blocking at the API boundary. Policy compliance is assessed before and after deployment, but outputs are not intercepted and stopped in flight. That distinction is what separates a governance documentation layer from an active enforcement layer, and it is the gap an operating model built for AI scale needs to close.
The Three Structural Archetypes: Centralized, Federated, and Hub-and-Spoke
The structural tradeoffs deserve more than a label.
Centralized
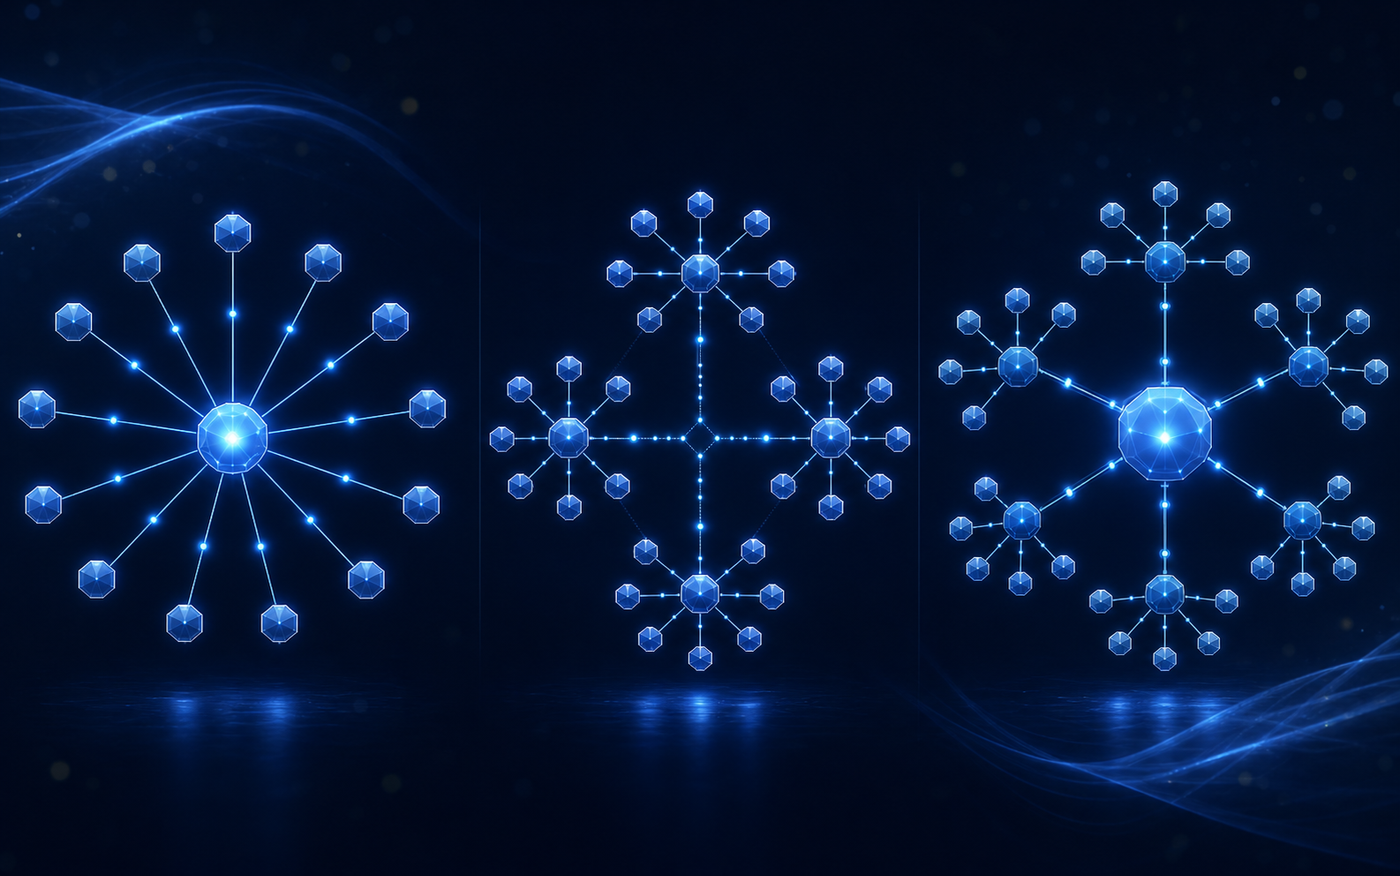
A single function owns AI risk policy, review, and approval. Every model, agent, or workflow passes through one committee before deployment. The upside is consistency: one risk standard, one audit trail, one enforcement point. The downside is throughput. As AI portfolios grow, that central function becomes a bottleneck, and teams route around it. High-compliance environments with limited AI scale are the natural fit.
Federated
Business domains own their governance end-to-end, each setting its own review criteria and deployment standards. Speed and domain expertise are real advantages. But without a shared policy floor, controls diverge fast: one team gates on fairness metrics; another doesn't. Federated models work where domains differ in risk profile, but they produce inconsistent evidence records that create problems at audit time.
Hub-and-Spoke
The center sets standards, maintains the inventory, and owns regulatory mapping. Domains execute against those standards and drive adoption. As one Gartner peer community contributor frames it: "business owns the outcomes; the centre provides the platforms, standards, and controls that allow AI to scale safely." It scales without fragmenting controls. The risk is coordination friction: if the central function moves slowly, domain teams face the same bottleneck as centralized governance, just one layer removed.
| Archetype | Standards | Execution | Best for |
|---|---|---|---|
| Centralized | Center | Center | Regulated, small AI portfolio |
| Federated | Domains | Domains | Diverse, decentralized orgs |
| Hub-and-Spoke | Center | Domains | Scaled enterprise programs |
The Five Structural Components of an AI Governance Operating Model
Any operating model that works in practice has five structural components. Organizations can document all the right principles and still fail governance audits because one of these five is either absent or lives only in a slide deck.
- Decision rights: Specifies who can authorize a deployment, which risk tier they can clear, and what evidence they need. A model owner can approve low-risk internal tools; high-risk systems touching customer data require sign-off from both the governance lead and legal. Without this, every contested deployment circles back to committee by default.
- Accountability matrix (RACI): Assigns Responsible, Accountable, Consulted, and Informed designations to named roles, not functions or teams. The data science lead is Responsible for evaluation results; the governance lead is Accountable for regulatory mapping; legal is Consulted before any EU AI Act Annex III deployment.
- Escalation paths: Defines what happens when a decision exceeds a reviewer's authority or stalls past its SLA. A model flagged for fairness issues needs a named path to the ethics committee with a time bound, not an informal Slack thread, the kind of escalation discipline SR 26-2 model risk management updates expect from AI teams.
- Enforcement mechanisms: Translates approved policy into automated controls at the workflow level. A documented PII policy enforced by a runtime guardrail that blocks non-compliant outputs before they exit the API boundary. Policy without a mechanism is aspiration.
- Review cadence: Schedules when the operating model itself gets updated, quarterly at minimum, and triggered by new regulatory obligations or a new model type entering production.
Who Owns What: Defining the RACI Across Key Roles
A RACI only works if the roles holding each designation actually have the authority to act on it. In enterprise AI programs, two failure points appear before anything else: no one owns the decision when a model crosses risk tiers, and the boundary between the CAIO and CDO is undefined enough that each assumes the other is accountable.
The CDO/CAIO overlap deserves direct resolution. Where both roles exist, the CDO typically owns data quality, data governance policy, and the underlying infrastructure AI systems draw from. The CAIO owns AI strategy, model portfolio decisions, and risk posture across deployments. But the authority boundaries blur the moment a data pipeline feeds a high-risk model, and neither role has an unambiguous claim on who signs off. The operating model must specify that explicitly, or the gap becomes the default escalation path.
- AI Steering Committee: Owns portfolio-level budget allocation, cross-domain prioritization, and final escalation for deployments no single function can clear. Holds authority to halt programs.
- CAIO: Accountable for AI risk posture organization-wide, framework selection, and the operating model itself. Owns the final call on high-risk system classification.
- CDO: Accountable for data readiness, lineage, and quality standards AI systems depend on. Responsible for flagging data governance gaps that affect downstream model risk.
- Legal and Compliance: Translates regulatory obligations into enforceable policy requirements. Consulted before any Annex III deployment or any system change that alters risk classification.
- Data and Engineering Teams: Responsible for implementing technical controls, including CI/CD gates, guardrail configuration, and evaluation thresholds. Accountable for keeping those controls current as models update.
- Model/AI Owners (business unit): Day-to-day accountability for deployed system behavior, drift thresholds, and incident escalation. The first named owner when a production failure surfaces.
The AI System Intake and Approval Workflow
Intake is where the operating model first proves whether it's real or decorative. A form that collects a model name and a business owner and routes everything to the same committee regardless of risk profile is not governance; it's paperwork.
A functioning intake workflow has four stages: submission, risk classification, routing, and decision with evidence capture.
At submission, the metadata collected must include model owner, intended use case, affected population, data sources and their regulatory category, deployment environment, and expected lifecycle stage. An auditor reviewing an incomplete intake record treats it as evidence the control was never in place, not that the team forgot to fill out a form, a distinction any usable AI risk assessment report has to anticipate.
Risk classification drives everything downstream. Low-risk systems move through a fast-track with a single sign-off and automated evaluation thresholds. High-risk systems, anything touching credit decisions, clinical recommendations, hiring, or insurance pricing, require multidisciplinary review: legal confirms regulatory category, privacy reviews data handling, security assesses the deployment environment, and compliance maps the system to applicable framework obligations before any approval is recorded.
That proportional routing separates intake from a rubber stamp. A model summarizing internal documents and a model scoring insurance applications should never follow the same path through the same committee at the same pace.
The decision gate produces an audit record, not merely a status flag. Approved systems carry a named approver, a timestamp, the risk tier assigned, and any attached conditions. A conditional approval requiring enhanced monitoring within 30 days of production is a governance decision; an approval with no conditions is a signal the review was cursory.
Regulatory Anchoring: Mapping the Operating Model to EU AI Act, NIST AI RMF, and ISO 42001
Each of these three frameworks imposes operating model obligations as part of a broader EU AI Act, NIST RMF, ISO 42001. None treats governance as optional best practice.
The EU AI Act is the most binding. GPAI provider obligations became enforceable in August 2025, with Annex III high-risk system obligations following August 2, 2026. Article 9 requires an active risk management system throughout the AI lifecycle, not a policy document that describes one. A risk assessment completed at deployment and never revisited does not satisfy Article 9. The operating model must specify when assessments recur, who triggers them, and what evidence gets recorded.
NIST AI RMF's Govern function is the closest structural analog to an operating model in any published framework. Teams that complete NIST mapping exercises often find it exposes the same gaps intake audits do: roles exist, responsibilities are vague, and no mechanism enforces the difference.
ISO 42001 functions as an AI management system standard, not a risk taxonomy. For organizations already holding ISO 27001 certification, compliance is meaningfully faster because the management system infrastructure carries over, meaning document control, audit cadence, and corrective action workflows can extend to AI-specific obligations instead of being rebuilt separately.
Where two or more frameworks require the same type of evidence, a single governance workflow can satisfy multiple obligations at once. Incident records, evaluation results, and deployment approval logs captured during normal operation become the evidence base for EU AI Act Article 12 record-keeping, NIST AI RMF accountability documentation, and ISO 42001 audit artifacts simultaneously.
Putting Controls Into Practice: From Policy to Automated Enforcement
Policy documentation names the requirement. The enforcement mechanism determines whether it holds.
Four points on the enforcement range describe most production AI controls: documentation records the rule, logging captures what happened, alerting notifies when a threshold is crossed, and blocking stops the output before it reaches its destination. The first three are observation; only blocking is enforcement.
Documentation and logging carry low execution cost and produce the audit records regulators ask to see, which is part of why runtime AI controls differ from documentation. But a logged PII exposure is still an exposure. Alerting is faster, though still post-hoc for outputs that execute in milliseconds. A monitoring alert that fires after an agent has written to a production database is evidence of a gap, not closure of one.
Blocking controls are the only posture that prevents, and does not merely record. CI/CD deployment gates that fail a merge when groundedness scores drop below a configured floor stop a non-compliant change before it reaches production. Runtime guardrails that intercept outputs at the API boundary stop a policy violation before the user sees it. That blocking step is what separates enforcement from observation.
The tradeoff is real: blocking controls introduce latency, require threshold calibration, and can generate false positives that interrupt legitimate workflows. A guardrail misconfigured too conservatively becomes a bottleneck that teams route around. Configurable enforcement actions, allow-with-logging for low-risk outputs, warn for borderline cases, block for confirmed violations, let organizations match enforcement posture to risk tier.
Human review queues sit between blocking and alerting: the output is held until a named reviewer clears it. This is meaningful for high-stakes outputs like clinical recommendations or financial guidance, where automated confidence alone is insufficient, though costly to run at scale.
Agentic AI Requires a Different Operating Model, Not Merely an Update
Traditional governance assumes a human or a system generates an output, a reviewer assesses it, and a decision follows. Agents break that sequence entirely, which is why production agent governance requires a distinct model. As the California Management Review observes, organizations deploying autonomous AI are finding that "existing governance and operating models are ill-suited to software that can independently perceive, decide, and act." A tool call against a production database executes before any reviewer can intervene. The output has already become an action.
Three operating model changes are required:
- Tool authorization with explicit allow lists: Every agent must have a registered scope of permitted tools. Invocations outside that scope are blocked before execution, not flagged after. A governance model that logs unauthorized tool calls after they fire has recorded the gap, not closed it.
- Sequence-level monitoring: Individual step evaluation misses compounding failures. An agent can pass each discrete check and still execute a sequence of actions that, in combination, violates policy.
- Audit trails sufficient for reconstruction: When an agent failure surfaces, the record must include the agent ID, tool requested, alignment score, task context, and the enforcement decision made at that moment.
A concrete example of how the implications compound: an agent with write permissions to a CRM and calendar system can execute a sequence of tool calls (read a contact record, draft an outreach email, schedule a follow-up meeting) that each pass an individual step check and collectively constitute an unauthorized data disclosure. No single call trips the policy threshold; the violation lives in the sequence. That is not a documentation gap or a logging gap. It is a governance model that was never designed for multi-step autonomous execution.
Scaling Governance Without Becoming a Bottleneck
Proportionality is the design lever. A model summarizing internal meeting notes and a model scoring mortgage applications should not clear the same review workflow. Low-risk systems can fast-track with automated evaluation thresholds and a single named approver. High-risk systems require multidisciplinary sign-off, and that additional friction is the control working correctly, not a process failure.
Centralized standards with federated execution is what makes proportionality sustainable at scale. The center maintains the risk classification schema, the policy floor, and the regulatory mappings. Business domains execute against that standard without routing every decision back to a central committee. Teams move at their own pace within a shared guardrail.
The real design question is distinguishing necessary friction from bureaucratic overhead. A deployment gate that blocks a high-risk system with unresolved fairness flags is necessary friction. A two-week review queue for a low-risk internal tool is overhead that will generate workarounds, which is the balance shipping AI faster with governance gates is meant to strike. The operating model design work is specifying which friction belongs where, not eliminating it uniformly.
How Openlayer Connects the Operating Model to Active Enforcement
Openlayer is the unified evaluation, observability, and governance platform that makes the operating model run at production speed, and in practice, beyond paper.
AI system registration starts at intake. Compliance teams register systems, collect structured metadata via a configurable form builder, and maintain a centralized AI asset catalog without API access. Multi-dimensional risk scoring across impact scope, failure severity, observability, and regulatory exposure produces a composite score that determines which governance workflow fires next. Low-risk systems fast-track; high-risk systems route to multidisciplinary review automatically.
Each lifecycle stage supports configurable sign-off requirements: named approvers, required evidence artifacts, and stage-gate checklists before promotion. When a model owner approves a deployment, that approval is timestamped, attributed, and written to the audit trail.
The five-action enforcement taxonomy converts approved policy into runtime decisions at the API boundary: allow with logging, warn, block, redact, and escalate. An output crossing a PII threshold gets redacted; a clinical recommendation with low confidence gets held and routed to a human reviewer. The enforcement decision and its evidence record are generated together.
Over 175 pre-built tests cover accuracy, safety, and security, with automated compliance mapping to EU AI Act, NIST AI RMF, and ISO 42001. Test results and enforcement decisions populate the same audit trail, so the evidence base for a conformity assessment is a byproduct of normal operation, not a separate assembly effort. That is the premise behind continuous compliance evidence for AI systems.
Final Thoughts on Turning AI Governance Into a Working Reality
The structural components covered here, decision rights, RACIs, escalation paths, enforcement mechanisms, and review cadence, are not a checklist to complete once. They are the moving parts your governance model depends on every time a new system enters review. Getting them right early means your program scales without rebuilding accountability from scratch later. Reach out to the Openlayer team to see how active enforcement and automated compliance mapping fit into the model you're building.
FAQ
What's the difference between a hub-and-spoke AI governance operating model and a federated one?
In a hub-and-spoke model, the center owns the policy floor, risk classification schema, and regulatory mappings, while business domains execute against those standards independently. In a federated model, each domain sets its own review criteria and deployment standards end-to-end. The practical difference surfaces at audit time: federated models often produce inconsistent evidence records because one team gates on fairness metrics while another doesn't, whereas hub-and-spoke keeps controls consistent across the portfolio even as teams move at their own pace.
How do I build an AI governance operating model that covers agentic AI without creating a review bottleneck?
The starting point is three structural changes specific to agents: register every agent with an explicit allow list of permitted tools and block invocations outside that scope before execution, not after; monitor at the sequence level instead of the individual step, since an agent can pass each discrete check and still execute a policy-violating chain of actions in combination; and require audit trails that capture the agent ID, tool requested, alignment score, and task context at the moment of enforcement, not reconstructed after the fact. For throughput, keep low-risk agent tasks on fast-track with automated thresholds and reserve multidisciplinary review for agents with access to regulated data or external write permissions.
What should an AI governance operating model RACI actually specify?
A governance RACI only works when it assigns authority to named individuals, not functions, and specifies the evidence required to exercise each decision right. The CDO/CAIO boundary is the most common gap: where both roles exist, the CDO typically owns data quality and lineage, while the CAIO owns risk posture and framework selection, but neither has an unambiguous claim on a data pipeline feeding a high-risk model. The operating model must resolve that boundary explicitly. Model owners hold day-to-day accountability for deployed system behavior and drift thresholds; legal and compliance are consulted before any EU AI Act Annex III deployment or any system change that alters risk classification.
What AI governance audit evidence do I need for an EU AI Act conformity assessment?
The evidence base for a conformity assessment covers four categories: technical documentation under Annex IV (system architecture, training data provenance, performance metrics, known limitations, risk management procedures); per-request audit records capturing the metric score, threshold checked, policy rule triggered, and timestamp for each inference; incident records generated automatically when a guardrail fires or a metric score falls outside its approved range; and deployment approval logs naming the approver, timestamp, risk tier assigned, and any attached conditions. When these records are produced as a byproduct of normal enforcement operation instead of assembled separately, a single governance workflow can satisfy EU AI Act Article 12 record-keeping, NIST AI RMF accountability documentation, and ISO 42001 audit artifacts at the same time.
How does Openlayer compare to Langfuse or Arize AI for enterprise AI governance?
Langfuse and Arize AI are observability platforms: they trace prompts, agents, and tool calls, and surface quality and drift signals for engineering teams. Langfuse provides strong prompt versioning, experiment tracking, and cost monitoring; Arize offers production monitoring, embedding drift detection, and model performance dashboards that are genuinely useful for ML teams managing deployed models. On runtime enforcement, however, both platforms are primarily observability-first: Langfuse delegates enforcement to third-party libraries such as LLM Guard and NeMo Guardrails instead of blocking natively, and Arize's focus is on surfacing signals for human review, with no automated regulatory compliance mapping or API-boundary interception. Openlayer connects pre-deployment evaluation, continuous production monitoring, runtime guardrails that block or redact at the API boundary, and automated compliance mapping to EU AI Act, NIST AI RMF, and ISO 42001 in one platform. The structural distinction is that logging a PII exposure or a policy violation after it has reached a downstream system is observation; blocking it before the output exits the API boundary is enforcement.