How to Enforce Agentic AI Governance (October 2026)
You've defined what your agents should do. You've probably written a policy that says so. But a policy document with no enforcement mechanism doesn't stop an agent from calling a tool outside its permitted scope. It just gives you something to point to afterward. Getting agentic AI governance right means moving the control point from documentation to execution, and that shift is more specific than it sounds.
TLDR:
- Agentic AI governance requires blocking tool calls before execution, not logging them after: an alerted database write has already committed
- Only 21% of enterprises have mature governance models for autonomous agents, and 40% of agentic AI projects are projected to fail by 2027 due to inadequate controls
- Effective agentic governance starts with a registered allowlist naming permitted tools by name and version; a narrative policy document cannot be enforced at runtime
- EU AI Act Articles 9, 14, and 15 impose active risk controls, human oversight, and prompt injection defenses on agentic deployments, with fines up to €15 million or 3% of global annual turnover under Article 99(3)
- Openlayer enforces agentic governance at the API boundary with five consequence-calibrated actions (allow, warn, block, redact, or escalate) before tool calls reach live systems
What Makes an AI System "Agentic" and Why It Changes the Governance Problem
A standard AI system responds. You send it a prompt, it returns an output, and the interaction ends. The model holds no state, takes no further action, and touches nothing else in your environment.
An agentic AI system does something structurally different: it receives a goal and then plans, reasons, and executes a sequence of steps to achieve it. That execution involves calling tools, querying databases, reading files, writing records, and invoking external APIs. Each step produces state that informs the next. The agent decides what to do at each decision point without a human reviewing the choice first.
That distinction matters enormously for governance. A generative AI model that produces a bad response is a content problem. An agent that takes a bad action has already changed something in your production environment. A tool call fired against a customer database, a write committed to a billing record, a POST sent to a third-party API: those events have already occurred. Logging them afterward is not a control; it is a record of what you failed to prevent.
With generative AI, the control point is the output before it reaches a user. With agents, the control point is the action before it executes against a live system. The window between an agent's decision and its downstream consequences is measured in milliseconds, not review cycles.
Why Traditional AI Governance Fails for Agents
Traditional AI governance was built around a simple assumption: the model produces an output, a human decides what to do with it. Documentation, audit trails, and policy reviews all work because there is time between the model's output and any consequential action. That time is where governance lives.
Agentic systems collapse that window. The research paper "Governing the Agentic Enterprise" found that only 21% of enterprises have mature governance models for autonomous agents, and 40% of agentic AI projects are projected to fail by 2027 due to inadequate governance and risk controls. Those numbers reflect a structural mismatch, not a tooling gap.
Observe-and-log governance has three specific failure points with agents:
- Logging captures what happened after an action executed against a live system. The record is accurate; the harm is already done.
- Static policy documents define what agents should do but carry no mechanism to stop what they actually do at inference time.
- Periodic compliance reviews assume a stable system between reviews. Agents can accumulate permissions, call unapproved tools, and modify shared state across thousands of interactions before any review cycle catches it.
The deeper problem is that traditional governance treats the model as the boundary. For agentic systems, the boundary is the tool call, the external API, the database write. Governance frameworks that stop at the model output have already missed the control point that matters.
The Primary Risks of Agentic AI Systems
Six risk categories define the agentic governance problem. Each is structurally distinct from what generative AI alone produces.
- Unauthorized tool invocation: An agent calls a tool outside its permitted scope (a billing API, a customer record endpoint, an admin function) because its instructions were ambiguous or because a prompt injection redirected its goal. The call executes before any review layer sees it.
- Privilege escalation: An agent accumulates permissions across a session or across tool chains, ending up with access well beyond what its original authorization granted, often through chained tool calls that each appear individually legitimate.
- Data misuse in retrieval pipelines: In RAG-based agentic systems, retrieved chunks may contain PII, confidential records, or regulated data that the agent passes into tool call arguments or external API payloads before any output-layer guardrail intercepts it.
- Emergent multi-agent effects: The OWASP Agentic AI Security and Governance identifies agent sprawl as a distinct systemic risk, where redundant, ungoverned agents proliferate across business functions, producing conflicting actions and cascading failures no single agent's governance covers.
- Accountability diffusion: When five agents collaborate on a workflow, responsibility for a harmful output is distributed across the chain, making post-incident attribution difficult and satisfying regulatory accountability requirements structurally harder.
- Silent behavioral drift: Agent behavior changes over time as context windows fill, tool availability changes, or upstream model updates propagate. Unlike a classification model whose accuracy degrades detectably, an agent's behavioral drift can stay subtle enough to evade threshold-based alerts for weeks.
How Agentic AI Governance Differs from Traditional AI Governance
The table makes the structural shift visible: traditional governance is output-centric because the model's output is where risk surfaces, while agentic governance is action-centric because the tool call is where risk executes. Reviewing an output after the fact carries no consequence when the output is just text. Reviewing a tool call after the fact means the database write already happened.
| Dimension | Traditional AI Governance | Agentic AI Governance |
|---|---|---|
| Control point | Output before user sees it | Tool call before it executes |
| Review window | Post-generation, pre-action | Milliseconds before irreversible state change |
| Governance documentation | Covers model behavior and intended outputs | Must cover tool scope, delegation authority, and action boundaries |
| Production monitoring | Drift in output quality and distribution | Drift in tool selection, permission accumulation, and multi-step goal adherence |
| Runtime enforcement | Block or redact unsafe outputs at the API boundary | Block unauthorized tool invocations before execution against live systems |
Regulatory and Industry Frameworks Shaping Agentic Governance
Three frameworks now define the baseline for agentic governance practice.
Singapore's IMDA Model AI Governance Framework (Version 1.5, May 2026)
Updated in May 2026 after feedback from over 60 organizations, the framework retains four pillars: assess and bound risks upfront, make humans meaningfully accountable, implement technical controls, and give end-users clear responsibility. Version 1.5 added targeted guidance on multi-agent systemic risks, including agent sprawl, and expanded technical control requirements beyond the original. It is the most detailed public framework written for agentic deployments in practical terms.
Pillar 2 in practice: in a credit-scoring workflow where a supervisor agent delegates sub-tasks to worker agents, a named human approver must be logged at every delegation hop: the approver's identity, the specific action authorized, and the timestamp recorded as a structured audit entry before the next agent in the chain executes. That log is not a post-hoc trace; it is the governance artifact the framework requires to establish meaningful human accountability at each decision boundary.
OWASP State of Agentic AI Security and Governance 2.01 (June 2026)
The June 2026 report moves from speculative threat modeling to evidence-based risk documentation, drawing on confirmed incidents across all ten risk categories. It introduces an agent taxonomy, a live incidents tracker, and new sections on agent identity and supply chain provenance. Its central finding: safety and security failures meet at the deployment layer, and governance capability is falling further behind deployment speed.
EU AI Act: Articles 9, 14, and 15 (August 2026 Deadline)
Three articles carry direct agentic governance implications for high-risk systems. Article 9 requires an active risk management system throughout the lifecycle, covering tool scope and authorization boundaries. Article 14 mandates human oversight with the practical ability to intervene before agent actions become irreversible. Article 15 requires ongoing accuracy and robustness measures, including controls against prompt injection. Non-compliance carries fines up to €15 million or 3% of global annual turnover under Article 99(3).
Defining Agent Scope and Authority Before Deployment
Governance controls that fire at runtime can only enforce what was defined before deployment. If an agent's permitted tool set was never explicitly specified, there is nothing to enforce against.
Assessing agentic AI risk before deployment starts with answering three questions for every agent before it touches a production system:
- Which tools is this agent permitted to invoke, by name and version?
- Which data sources and endpoints can it read from or write to?
- What decisions can it make autonomously, and at what threshold does a decision require human sign-off?
The answers become a registered allowlist, not a narrative policy. A document that says "the agent should only access customer records relevant to the current session" is not enforceable. An allowlist that names get_customer_record, update_case_status, and blocks delete_customer, export_bulk_records, and any billing endpoint is. That distinction is the difference between a governance policy and a governance control.
Scope should be bounded to the minimum required for the agent's stated task, then registered as a versioned artifact tied to the agent's identity. When the task changes, the allowlist changes through a governed update process with a named approver, not through an informal prompt modification.
Identity and Access Controls for AI Agents
Every enterprise IAM system treats AI agents as either users or service accounts, a category error that internal AI risk classification is designed to fix. That category error is where permission creep begins.
An agent needs its own identity, scoped to its registered allowlist, with credentials that expire and rotate independently of the human account that invoked it. When an agent inherits a user's permissions through a shared service account, it inherits everything that account can access. The agent's actual task might require three API calls; the inherited account might permit three hundred.
There are two compounding failure modes here.
- Least-privilege violations at the individual level: credentials scoped to a human or service account instead of the specific tools and endpoints in the agent's registered allowlist.
- Inheritance cascades in multi-agent chains: a supervisor delegates to a worker, the worker needs a tool the supervisor can access, and without explicit scope transfer controls, the worker inherits the supervisor's full permission set. Repeated across four or five agents, that pattern deposits broad access in a terminal agent built for a narrow task.
The OWASP GenAI Security Project flagged "the difference between agent identity and non-human identity" as one of the most underdeveloped areas in current enterprise deployments in its 2026 OWASP Agentic AI Governance report.
The tradeoff is genuine: narrow scopes reduce risk but make agents brittle, where a single missing tool call breaks the workflow. The practical path is starting with the narrowest scope that completes the stated task, then expanding through a governed change process with a named approver and an updated allowlist version.
Pre-Deployment Governance Gates for Agentic Systems
Pre-deployment governance for agents differs from running an eval suite before shipping. An eval checks whether the agent performs well on representative inputs. A governance gate checks whether the agent is authorized to do what it does at all, and whether known failure modes have been surfaced and accepted before any real action executes.
Four checks belong at the gate:
- Scope verification against the registered allowlist: confirm that every tool the agent invokes in test conditions appears in its registered allowlist. Any tool call that appears in evaluation traces but not in the allowlist is a misconfiguration finding, not a performance finding.
- LLM red-teaming attack vectors like prompt injection resistance testing: adversarial inputs designed to redirect the agent's goal belong in the pre-deployment test set. An agent redirected to call an unauthorized endpoint via a crafted user message has a security failure, not an accuracy failure.
- Tool-call correctness evaluation: test whether the agent passes correct arguments in the right context. Semantic tool errors, where a valid tool is called with valid arguments in the wrong situation, are the class that schema validation misses entirely.
- Threshold-gated deployment blocking: if tool-call accuracy falls below a defined threshold, or intent-to-tool alignment confidence drops below the enforcement floor, the deployment gate blocks promotion. A hard CI/CD block that prevents the agent from reaching production unless thresholds pass is a gate; a soft recommendation that a human reviews results is not.
The gate is also where the agent's impact profile gets documented: what data it can read, what systems it can modify, and what an authorization failure looks like in that specific deployment context. That documentation is not a policy statement; it is the evidentiary artifact that satisfies Article 9 risk management requirements before the agent's first real action.
Runtime Enforcement: The Control Point That Matters for Agents
Documentation tells you what the agent should do. Logging tells you what it did. Alerting tells you something went wrong. Blocking stops it before it happens. Only one of those is enforcement.
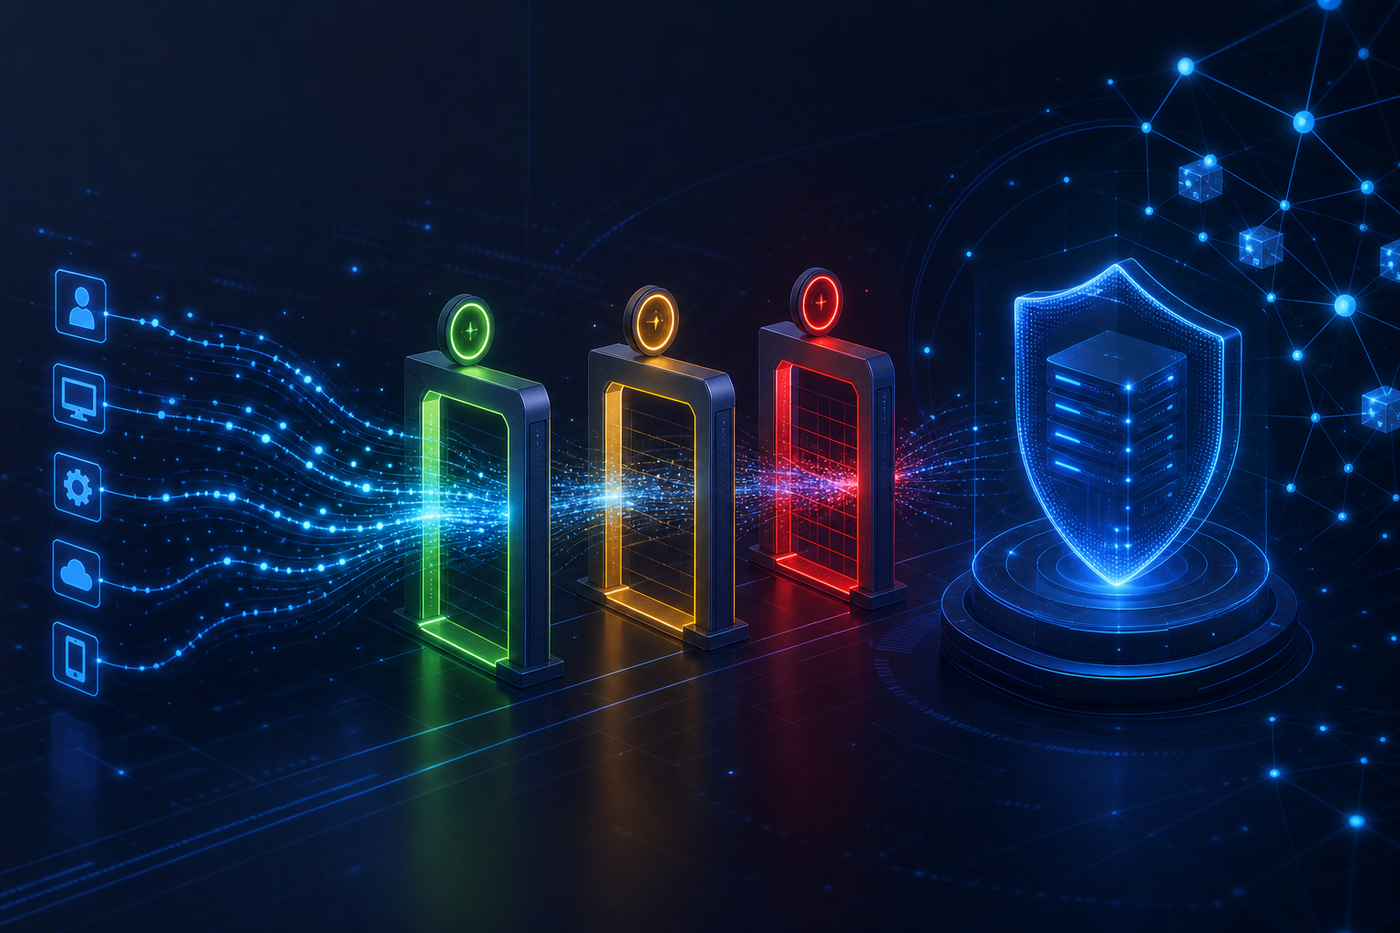
The control that matters is blocking: suspending execution before the tool call reaches a live system. Openlayer's runtime enforcement layer exposes five discrete actions at the API boundary, each calibrated to the consequence profile of the tool call in question:
For agentic systems, the distance between alerting and blocking is not a configuration detail. An alerted tool call against a billing API has already committed a write. An alerted data export has already transmitted PII to a downstream system. The alert is accurate. The harm is done.
Openlayer's runtime enforcement layer exposes five discrete actions at the API boundary:
- Allow with logging: the tool call is permitted and fully traced. Use for low-risk, high-frequency calls where audit coverage matters but blocking would add latency without reducing real risk.
- Warn: the call passes through but flags a policy deviation for review. Use when the tool is on the allowlist but the argument payload matches a pattern associated with misuse.
- Block: execution is suspended before the call reaches the target system. Use when the requested tool sits outside the agent's registered allowlist or when intent-to-tool alignment confidence drops below 0.75, a default starting threshold to calibrate against your deployment's consequence profile.
- Redact: sensitive content in tool call arguments is masked before execution. Use when PII passes through argument payloads in retrieval pipelines before any output-layer guardrail can intercept it. Tool-calling guardrails and retry patterns govern how each of these enforcement actions is applied consistently.
- Escalate: the request is held and routed to a human reviewer before the call fires. Use when automated confidence is insufficient and the target action carries direct liability, such as an agent initiating a financial transaction or modifying a regulated record.
Each block event generates an audit trail entry carrying the agent ID, the requested tool, the alignment score, and the task context. That record is produced as a byproduct of enforcement at the moment of action, not assembled afterward from log data.
Logging, Audit Trails, and Session-Level Traceability
Per-turn logging records what an agent said at each step. Sequence-level monitoring reconstructs what it did across the full execution path, and why.
That distinction is load-bearing for multi-step agent workflows. A log entry showing tool_call: get_customer_record tells you the call happened. A sequence-level trace showing the goal the agent received, the intermediate reasoning steps, the authorization context at call time, the arguments passed, and the downstream state change. That level of detail (covered in AI agent observability tracing) tells you whether the call was within scope, whether the argument payload exposed PII, and whether the outcome matched the original task specification. Only the second constitutes an adequate audit record.
An adequate audit trail for an agentic deployment contains five elements per action:
- The agent ID and the task context that initiated the session
- The tool requested, the arguments passed, and the timestamp of the invocation
- The authorization state at the moment of execution: was the tool on the registered allowlist, and what was the intent-to-tool alignment score
- The result returned and any state change the call produced in an external system
- The enforcement action taken: allowed, warned, blocked, redacted, or escalated
What that record makes possible is session-level reconstruction: given any agent incident, you can identify the exact decision point where the workflow deviated, which tool invocation produced the harmful state change, and whether a governance control was in place at the moment of action. Post-hoc log review that cannot reconstruct that chain is evidence of a tracing gap, not an audit trail.
Openlayer's AI-generated trace summaries surface this reconstruction for non-technical reviewers, so compliance officers and risk managers can read a plain-language summary of tool calls, agent handoffs, errors, and final outcomes without parsing raw span data, while the underlying trace retains the full structured record for regulatory examination.
Human Oversight Thresholds and the Escalation Path
Automated enforcement handles the clear cases. The agent requests a tool outside its allowlist: block. The prompt injection classifier exceeds, for example, 0.85 confidence: flag and route to secondary review. Intent-to-tool alignment drops below 0.75: suspend execution.
The harder cases are where the tool is permitted, the arguments look valid, and the confidence score clears the threshold, but the decision itself carries direct liability if the output is wrong. Confidence is not the same as correctness, and for certain output categories, an incorrect automated decision produces harm that no subsequent remediation undoes.
Four categories warrant mandatory human review regardless of confidence score:
- Clinical decision support outputs influencing active treatment recommendations
- Legal document review flagging liability clauses or contract terms
- Financial planning guidance generating personalized investment recommendations
- Benefits eligibility determinations affecting access to regulated public services
For everything outside those categories, escalation thresholds need to be configured before deployment. A starting framework: route to human review when AI risk scoring across groundedness, tool-argument validity, and task-goal alignment falls below 0.80 on any single action affecting external state. Calibrate that figure to the consequence profile of your specific deployment and document the rationale as part of the Article 9 risk management record.
The tradeoff is real. Raise the threshold too high and you create a review queue no team can staff at production volume. Set it too low and reviewers are approving outputs too quickly to add genuine oversight. The right threshold is the one where a reviewer has enough context and time to make a substantive decision before the action fires.
Override decisions must be logged with the reviewer's identity, the action approved or rejected, the timestamp, and a brief rationale. An override with no rationale is not a governance record; it is a click. EU AI Act Article 14 requires that human oversight be meaningful, not nominal, and a log showing approval in under two seconds with no documented basis will not satisfy that requirement under examination.
Governing Multi-Agent Systems and Delegation Chains
Multi-agent architectures make each governance step multiplicatively harder than single-agent deployments.
In a supervisor-worker hierarchy, each delegation hop risks scope creep: a terminal agent built to summarize a document may accumulate write access across four hops because workers inherit permissions instead of receiving only what their subtask requires. Peer-to-peer orchestration produces a different failure pattern, where a compromised agent injects instructions into shared state that redirect peer agents toward unauthorized actions.
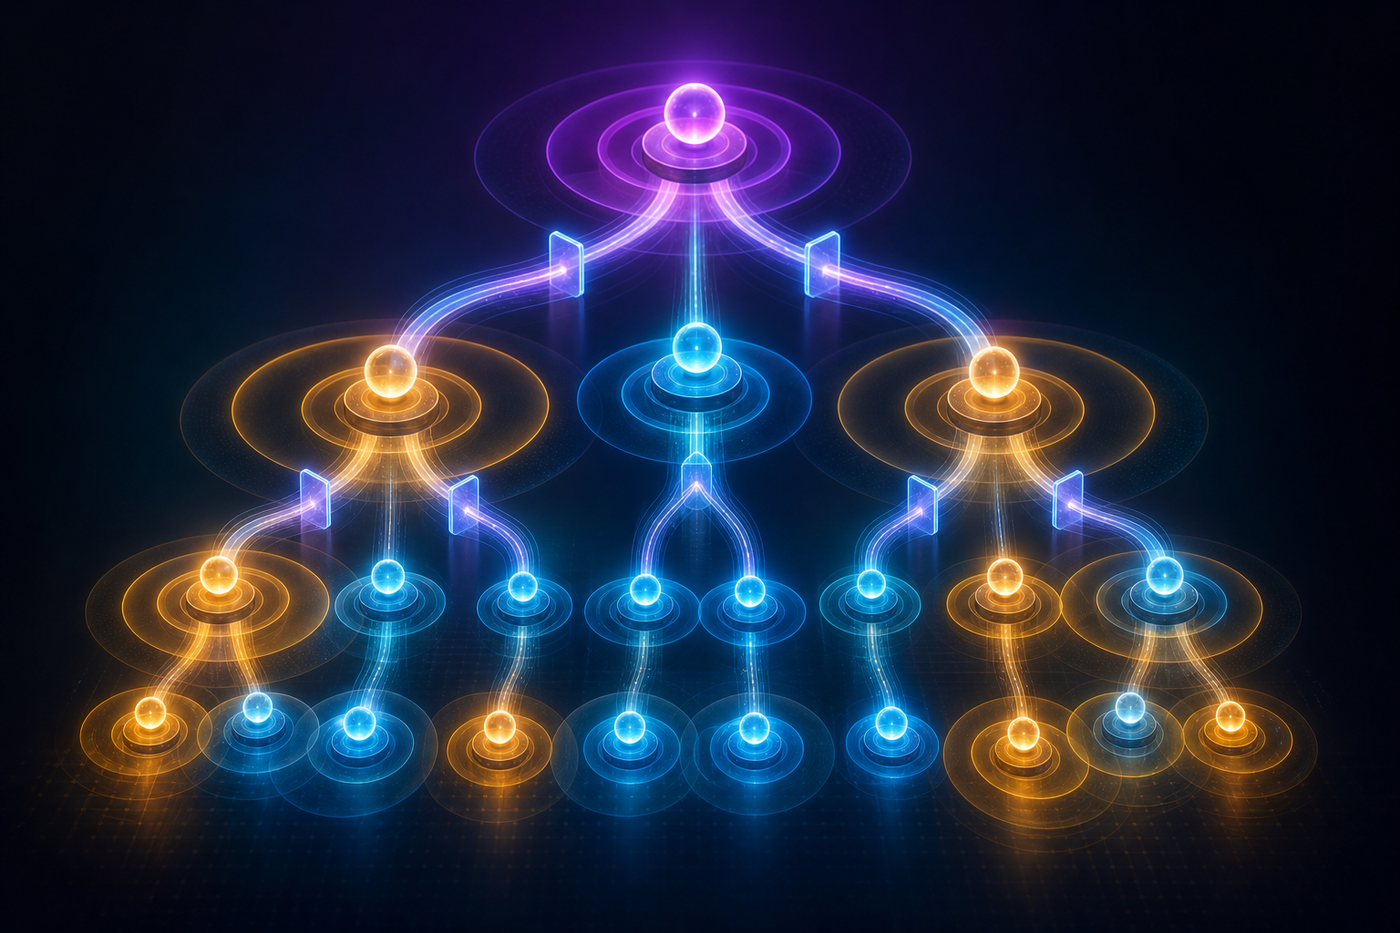
Three controls belong at every delegation boundary:
- Explicit scope transfer documentation: each delegation event records which permissions were passed, which were withheld, and which tool calls were authorized for that specific subtask only.
- Per-hop authorization validation: the receiving agent's allowlist is checked independently at each step, not inherited transitively from the calling agent's verified scope.
- Shared-state integrity checks: before an agent acts on context passed from a peer, verify the content hasn't deviated from the supervisor's original task specification.
The OWASP Agentic Security Initiative identifies a distinct organizational risk alongside these per-chain controls: redundant, ungoverned agents proliferating across business functions. An organization that governs every agent it knows about while losing track of which agents exist has bounded a known subset of the problem, not solved it. Inventory completeness is a precondition for everything else in multi-agent governance.
Incident Response and Shutdown Mechanisms for Agents
Four mechanisms need to be staged before any agent reaches production. Incident response for agents fails when it is designed after the first incident, not in advance of it. By the time an agent has fired an unauthorized tool call or entered a cost-burning loop, the response window is already compressed to seconds.
- Containment: a runtime kill-switch that halts inference immediately, rerouting subsequent requests to a fallback or human queue without dropping them. This is a hard stop enforced at the API boundary before the next action executes, not a soft disable waiting for the current session to complete.
- Rollback: a version revert to a prior validated agent configuration, including the specific allowlist, prompt version, and tool scope that passed pre-deployment gates. Rollback to a registered, tested artifact is a control; rollback to a policy document that "should" bound the agent is not.
- Impact assessment: using sequence-level trace data to reconstruct which tool calls executed before containment, in what order, against which systems, and with what arguments. That trace record answers the question regulators will ask: what changed in production before the agent was stopped?
- Regression test conversion: every production failure that surfaces a new failure mode gets converted into a test case before redeployment, building continuous compliance evidence as a byproduct. An agent stopped for calling an unauthorized billing endpoint produces a regression test that fails if any future version exhibits the same call. Redeployment without that test is a policy statement; redeployment with it is a control.
Severity classification determines how fast each step moves. A confirmed unauthorized tool call against a production system with external state changes is Critical: suspend within seconds, notify the Model Owner and Governance Lead within one hour, and do not resume inference until root cause is documented and the regression test passes. Behavioral anomalies without confirmed external impact are High: enhanced monitoring, investigation within 24 hours, no suspension unless the pattern escalates.
Ongoing Monitoring and Drift Detection for Agentic Deployments
Agents don't break cleanly. They drift.
Input drift (changes in the query distribution an agent receives) is detectable with standard statistical monitoring. Behavioral drift is harder: the agent receives similar inputs but chooses different tools, passes different argument payloads, or deviates from its original task path in ways that accumulate quietly across thousands of sessions before any threshold trips.
For response-only models, behavioral drift produces a worse answer. For agents, it produces a different action against a live system. A customer service agent that begins routing refund requests through an admin endpoint instead of the approved billing API has drifted behaviorally, and that deviation is invisible to output-quality metrics scoring only the text the user sees.
Three monitoring signals belong in any ongoing agentic governance program:
- Tool selection frequency by session type: if the distribution of which tools an agent invokes changes meaningfully for a given input category, that change warrants investigation before assuming it reflects appropriate adaptation.
- Argument payload patterns: monitor for new patterns developing in what agents pass to permitted tools, such as PII surfacing in fields that previously carried only anonymized identifiers, or scope-expanding query parameters appearing in read calls that previously stayed bounded. High-risk AI drift detection covers how to surface these changes before they accumulate.
- Goal-to-outcome alignment across sessions: measure whether the agent's final output matches the original task specification at the session level, beyond the individual turn level. Sequence-level monitoring catches cases where per-step quality scores pass while the overall workflow drifted from its stated goal.
Governing high-volume agentic output at scale has a cost structure that linear sampling can't solve. Configurable sampling (running intensive behavioral evaluations on representative subsets while maintaining full trace capture) lets governance scale without proportional cost growth. But sampling means some behavioral drift goes undetected between cycles. Setting sampling rates against the consequence profile of each tool category, instead of applying a uniform rate across the whole system, narrows that gap where it matters most.
Agentic AI Governance in Regulated Industries
Three sectors carry the highest consequence when agentic governance fails. Each has distinct regulatory obligations that documentation alone cannot satisfy.
Financial services faces two overlapping frameworks. EU AI Act high-risk system obligations cover AI used in credit scoring, fraud detection, and insurance pricing, with the August 2026 enforcement deadline now live. Articles 9, 14, and 15 require active risk controls, human override capability, and ongoing robustness measures. SR 11-7 model risk management requirements add a parallel obligation: pre-deployment validation results and flagged failure modes must form an evidentiary record a model validator can review. For agentic systems executing credit decisions, tool call logs and sequence-level traces constitute that record.
Healthcare adds a clinical decision support escalation requirement that overrides automated confidence thresholds entirely. Any agent output influencing an active treatment recommendation routes to human review before delivery, regardless of alignment score. Incident documentation carries four mandatory elements: the exact input values and preprocessing steps at inference time, the raw model output with version hash, the clinician-validated expected output, and a root cause classification. Under the EU AI Act, serious incidents resulting in patient harm carry a 15-day reporting obligation under Articles 61 and 72.
Public sector deployments face accountability diffusion as the primary governance risk. When agents inform benefits eligibility determinations or enforcement decisions, responsibility must be assigned to a named individual at each delegation hop. Every escalation threshold, override decision, and tool authorization must carry a named approver and timestamp. A governance program that answers accountability questions with agent IDs instead of human accountable parties has not met the requirement.
How Openlayer Handles Agentic AI Governance at the Enforcement Layer
Openlayer's agentic governance controls are built around a single architectural premise: the control point that matters is before the tool call fires, not after the trace is written.
Tool call authorization operates against a registered allowlist for each agent. When intent-to-tool alignment confidence drops below 0.75 (a default starting threshold, configurable to your deployment's consequence profile), or the requested tool sits outside the agent's registered scope, execution suspends and generates an audit trail entry carrying the agent ID, requested tool, alignment score, and task context automatically.
Sequence-level monitoring tracks tool calls, intermediate outputs, and state changes across the full execution path. Openlayer's 13 session-level metrics cover the complete interaction beyond isolated turns, so goal drift and permission accumulation that pass per-step checks become visible at the session level where they produce harm.
The five-action enforcement taxonomy gives teams consequence-calibrated responses: allow with logging for low-risk calls, warn for allowlisted tools with suspicious argument payloads, block for unauthorized invocations, redact for PII surfacing in tool call arguments, and escalate for actions carrying direct liability that automated confidence alone cannot clear.
Automated compliance mapping connects enforcement events to EU AI Act Articles 9, 14, and 15, NIST AI RMF, and ISO 42001 across the same 175+ pre-built tests running in pre-deployment evaluation. LLM-as-a-judge evaluation at 81.3% human correlation scales continuous governance to thousands of daily agent interactions, making compliance evidence a byproduct of normal enforcement operation, not a separate documentation exercise.
How IBM watsonx.governance and Credo AI Fit the Agentic Governance Stack
Two tools frequently appear in enterprise agentic governance conversations: IBM watsonx.governance and Credo AI. Both cover governance documentation within their respective domains, but neither crosses into active runtime enforcement at the API boundary.
IBM watsonx.governance covers AI governance and, within the IBM stack, partial monitoring. It does not currently block unauthorized tool invocations before execution, enforce intent-to-tool alignment thresholds at inference time, or redact PII surfacing in tool call arguments for multi-cloud or third-party LLM deployments. Credo AI coordinates policy workflows and risk documentation effectively but does not currently touch the model pipeline at runtime; it produces governance records, not enforcement events. For agentic deployments where the control point is the tool call before it fires against a live system, governance documentation and policy coordination operate at a different layer than runtime blocking.
Final Thoughts on Agentic AI Risk and Governance Frameworks
The governance gap for agentic AI is structural, not a tooling shortfall you can patch with better logging. Your agents need registered scope, per-hop authorization validation, and a blocking layer that fires before a tool call reaches a live system, not a policy document that describes what they should do. The frameworks and controls covered here give you the architecture; the implementation work is yours to sequence against the consequence profile of your specific deployment.
If you want to see how Openlayer's enforcement layer handles tool call authorization, escalation, and compliance mapping in practice, the team can walk you through it.
FAQ
What is agentic AI governance and how does it differ from traditional AI governance?
Agentic AI governance is the discipline of authorizing, monitoring, and enforcing what AI agents are permitted to do, beyond what they produce. Traditional AI governance is output-centric: the model generates text, a human decides what to do with it, and documentation and audit trails fill the gap between generation and action. Agentic governance is action-centric because the tool call, whether a database write, an API invocation, or a billing record update, is where risk executes, and that execution happens in milliseconds, before any human reviewer can intervene. The control point moves from "block the unsafe output before the user sees it" to "block the unauthorized tool invocation before it fires against a live system."
How do you maintain visibility and control over AI agent outputs when the volume of agent-created artifacts exceeds what humans can review?
Sequence-level monitoring is the mechanism that scales here: instead of reviewing each turn in isolation, you track tool calls, intermediate outputs, and state changes across the full execution path as a unit. This makes goal drift and permission accumulation visible at the session level, where they produce harm, even when per-step quality scores pass. Combine that with configurable sampling (running intensive behavioral evaluations on representative subsets, not full volume) and set sampling rates against the consequence profile of each tool category instead of applying a uniform rate across the system.
How does Openlayer integrate AI governance, real-time observability, and enforcement in a single platform compared to using multiple point solutions like IBM watsonx.governance or Credo AI?
IBM watsonx.governance and Credo AI cover governance documentation and, within IBM's stack, partial monitoring. Neither currently crosses into active runtime enforcement at the API boundary. IBM watsonx.governance does not currently provide real-time blocking of prompt injection or PII leakage for multi-cloud or third-party LLM deployments; Credo AI coordinates policy workflows without currently touching the model pipeline at runtime. Openlayer's structural differentiator is that the same policy definitions governing pre-deployment testing continue running as live enforcement gates in production: blocking unauthorized tool invocations, redacting PII surfacing in tool call arguments, and generating per-request audit records as a byproduct of normal enforcement operation, not as a separate documentation exercise.
What should an agentic AI governance framework include for enterprises deploying agents in regulated industries?
A governance framework for agentic deployments needs five layers working together: a registered allowlist defining which tools each agent can invoke by name and version; pre-deployment gates that block promotion if tool-call accuracy or intent-to-tool alignment falls below defined thresholds; runtime enforcement that suspends execution before unauthorized tool calls fire against live systems; sequence-level audit trails that reconstruct the full decision chain across all turns, beyond per-turn logs, for regulatory review; and human escalation paths for actions carrying direct liability, such as clinical recommendations, financial transactions, or benefits eligibility determinations. For EU AI Act high-risk system obligations with the August 2026 deadline now live, Articles 9, 14, and 15 each map directly to one of those layers: active risk controls, meaningful human override capability, and ongoing robustness measures including prompt injection resistance.
How do you build a multi-agent governance framework that enforces scope boundaries across delegation chains?
The core problem in multi-agent chains is permission inheritance: a terminal agent built for a narrow task accumulates broad access because workers inherit the calling agent's full permission set instead of receiving only what their subtask requires. Three controls belong at every delegation boundary: explicit scope transfer documentation recording which permissions were passed and which were withheld; per-hop authorization validation that checks the receiving agent's allowlist independently at each step; and shared-state integrity checks that verify context passed from a peer agent hasn't deviated from the supervisor's original task specification. Inventory completeness is a precondition for all of it: an organization that governs every agent it knows about while losing track of which agents exist has bounded a known subset of the problem, not solved it.